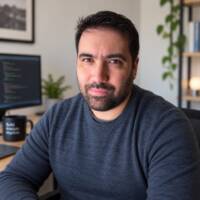
Daniel Thurman
Daniel Thurman

Senior Data Scientist and Software Engineer

Actively looking · Member since 15 Sep 2026
Location
Seattle, United States
Desired salary
150k–190k USD/yearly
Work preference
Hybrid / Full Time
Experience level
Senior

About

Professional summary

I am a senior data scientist and software engineer with 14 years of experience building production machine learning, statistical analysis, anomaly detection, and large-scale data systems.

I specialize in Python and SQL, with deep experience in behavioral analytics, imbalanced and incompletely labeled datasets, time-series analysis, model evaluation, and rigorous error analysis.

I have developed fraud, risk, reliability, and operational detection systems across fintech, cloud platforms, and scientific computing environments. My work spans research, feature engineering, offline evaluation, production deployment, monitoring, and ongoing model improvement.

I build cloud-native data and machine learning systems using AWS, GCP, Azure, Kubernetes, Docker, Terraform, Spark, Kafka, PyTorch, and scikit-learn.

I am experienced in translating ambiguous analytical findings into reliable product capabilities and operational recommendations. I also mentor engineers and data scientists on experimentation, evaluation standards, observability, and production engineering practices.

I have evaluated generative AI, RAG, and agentic systems for analyst-assistance workflows, including evaluation harnesses, prompt evaluation, investigation summaries, and risk-oriented applications.

Skills

27 capabilities

Tech stack & tools

Working toolkit

Application Hosting

Data Stores

Languages & Frameworks

Libraries

Experience

Career history

Senior Software Engineer Robinhood

Led development of behavioral risk models for suspicious account and transaction activity using Python, SQL, scikit-learn, anomaly detection, graph analytics, clustering, and statistical analysis. Designed evaluation methods for highly imbalanced datasets with incomplete labels, investigated false positives and false negatives, and improved detector precision while preserving emerging risk signals.

Built near-real-time feature pipelines from high-volume event streams with Kafka, Spark, PostgreSQL, and AWS. Productionized machine learning services using Docker, Kubernetes, Terraform, CI/CD, CloudWatch, dashboards, and automated validation. Mentored engineers and data scientists, documented model methodologies and tradeoffs, and evaluated OpenAI, GPT, Claude, RAG, and agentic systems for analyst-assistance workflows.
Software Production Engineer Meta

Analyzed large-scale service telemetry using Python, SQL, statistical analysis, and time-series methods to distinguish anomalies from expected infrastructure variation. Built anomaly-detection pipelines across distributed metrics and event streams, applying clustering and robust baselines where incident labels were incomplete.

Developed production data workflows with Python, Spark, Kafka, distributed systems, CI/CD, containers, Kubernetes, and GCP-style cloud infrastructure. Performed detector error analysis, created monitoring strategies for alert quality and behavioral drift, and contributed reusable analytical libraries, design reviews, and observability standards.

Senior Software Engineer Microsoft

Developed Python and SQL analytics for cloud-service telemetry, using statistical modeling and anomaly detection to identify unusual resource, authentication, and workload behavior. Built time-series features and classification workflows with scikit-learn, pandas, and distributed data pipelines, and designed offline evaluation datasets for noisy, rare, and incompletely labeled operational events.

Integrated analytical methods into production services using Azure, Docker, Kubernetes, Terraform, CI/CD, automated testing, and deployment safeguards. Investigated detector errors through feature-level analysis, log correlation, and controlled experiments, while documenting assumptions, experiments, and monitoring criteria for engineering teams.

Software Engineer Lawrence Livermore National Laboratory

Built Python and SQL analytical software for large scientific datasets, applying statistical analysis, clustering, time-series techniques, exploratory data analysis, anomaly detection, and signal processing. Developed workflows for sparse and noisy measurements with rare positive events and incomplete ground-truth labels.

Created maintainable data-processing services using Linux, Python, C++, batch pipelines, automated testing, and later containerized deployments. Supported production research systems through debugging, performance profiling, CI/CD automation, infrastructure scripting, and reproducible technical documentation.

Education

Learning history

University of the Pacific

Bachelor of Science (B.S.), Computer Science

Bachelor of Science in Computer Science.

This professional hasn’t added portfolio projects yet.

This professional hasn’t listed any services yet.

People also viewed

All talent ›
Jobs Talent AI Tools Salaries
Menu